Providers and models
NexgenK CLI supports connecting to multiple LLM platforms simultaneously: one-click login via the NexgenK managed service, connecting Claude with an Anthropic API key, or connecting third-party inference services via the OpenAI-compatible protocol. Each provider corresponds to a specific API protocol; models are declared on top of providers with their own name, context length, and capabilities. This page explains how to configure each type of provider in config.toml.
Supported provider types
The type field in the providers table determines which protocol implementation to use:
| Type | Protocol | Typical use |
|---|---|---|
nexgenk | OpenAI-compatible | NexgenK managed service, Nexgen Platform API key |
anthropic | Anthropic Messages | Claude model family |
openai | OpenAI Chat Completions | OpenAI and compatible services, DeepSeek, Qwen, etc. |
openai_responses | OpenAI Responses API | OpenAI's newer Responses interface |
google-genai | Google GenAI | Gemini API |
vertexai | Google GenAI on Vertex | Google Cloud Vertex AI |
All providers communicate with models in streaming mode by default. Capabilities such as thinking, vision, and tool use are matched automatically by model name prefix, so you typically do not need to declare them manually.
Credential priority: api_key or api_key_env (mutually exclusive alternatives — set exactly one) > [providers.<name>.env] sub-table key (only when neither is present) > if all are absent, startup fails with an error. Except for the explicitly declared api_key_env, the CLI does not fall back to shell environment variables for credentials. See Config overrides: provider credentials.
/provider — interactive provider management
Prefer not to edit TOML by hand? Type /provider in the TUI to open the provider manager, where you can interactively add or remove providers.
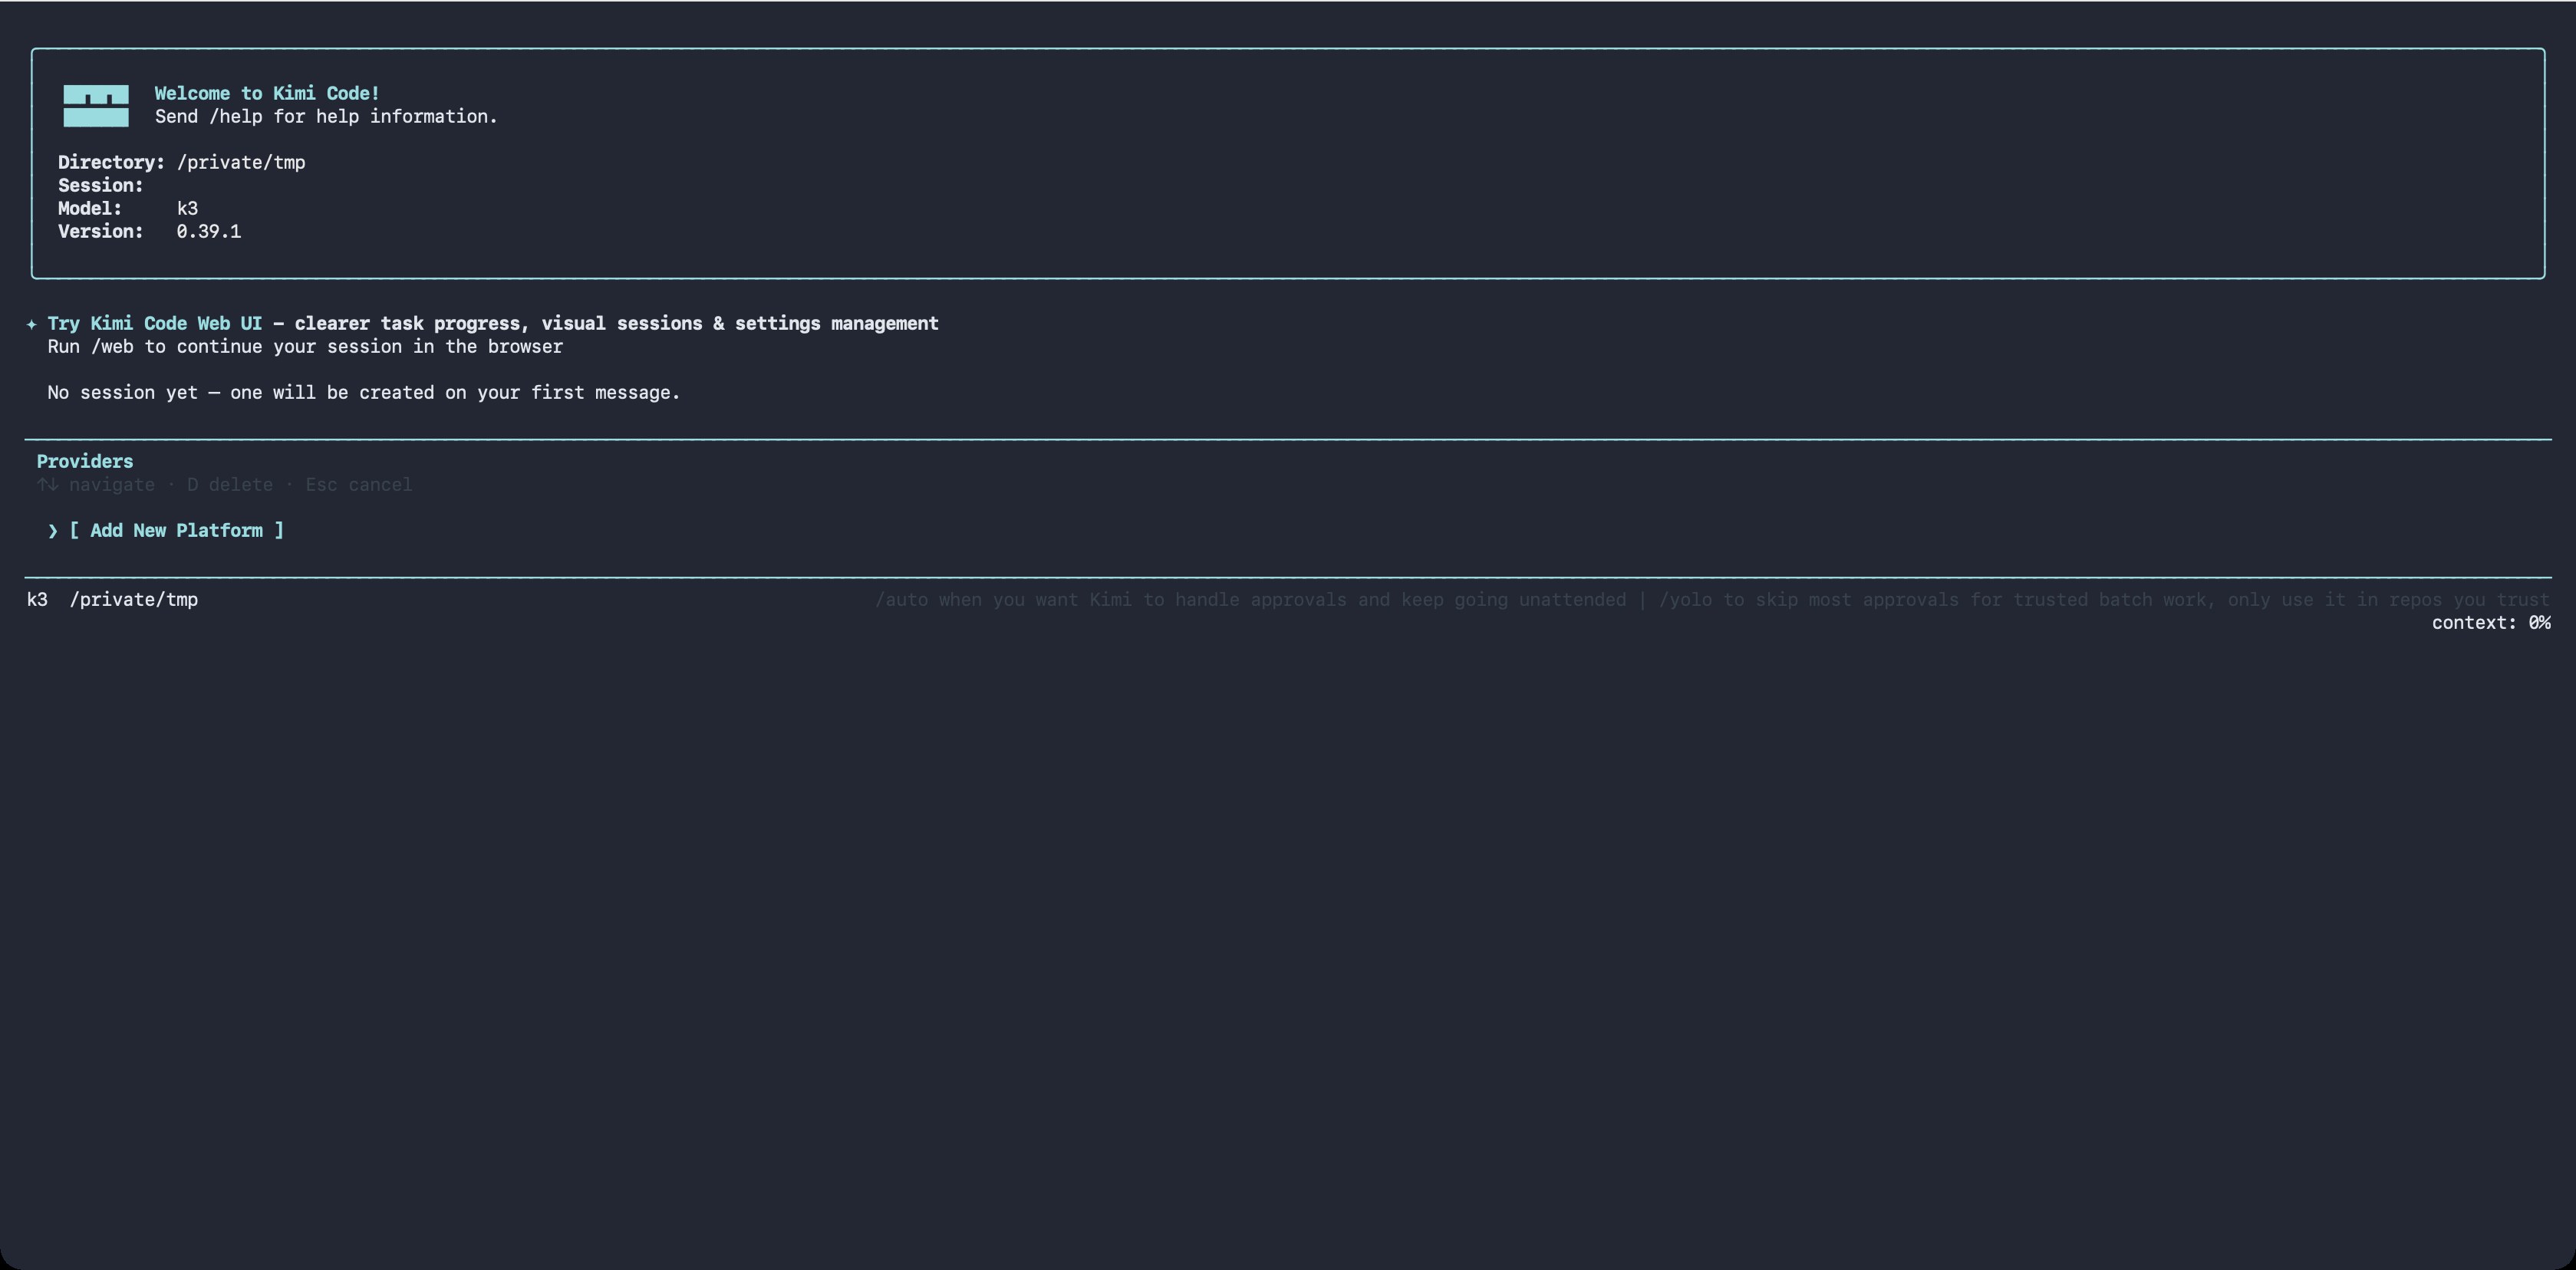
The manager displays providers as a list of entries grouped by source. Navigation:
- ↑/↓ to move the cursor, ←/→ to page
dto delete the current provider (with[y/N]confirmation)- Press Enter on the
[ Add New Platform ]row to add a new provider
Two paths when adding:
Known third-party provider: fetches the model catalog from models.dev, select a provider → enter an API key → select a default model. Vendors whose protocol the catalog does not declare (e.g. xai, openrouter, and other vendor-specific SDKs) are imported as OpenAI-compatible with a "guessed" note; when the catalog provides no usable endpoint, a base URL prompt appears first; proprietary protocols (Amazon Bedrock, Cohere) and unrecognized explicit protocols are refused. Deprecated and alpha-status models are excluded from the import list. If the public catalog is unreachable, the CLI falls back to a built-in snapshot of the catalog, so the import still works offline or in blocked networks
Custom registry (api.json): paste a custom registry URL and, for private registries, a Bearer token; the CLI automatically creates the
providers/modelsentries. When a registry entry declares theenvfield (the name of the environment variable holding the API key), the CLI prints it as a hint — setapi_key_envinconfig.tomlyourself to use it. The binding is never automatic: the registry chooses both the variable name and the endpoint the credential is sent to, so it must not decide which of your secrets is read. For private registries the Bearer token itself is still stored assource.apiKeyso the registry can be refetched on refresh. On later startup, providers from the same registry URL are refreshed together, so upstream provider additions, removals, and model metadata changes are synced.A registry model may also declare an
upgradeobject.modelselects the replacement model in the same provider,migration_markdownsupplies the explanation shown during migration ({model_from}and{model_to}in it are replaced with the model ids on import), andretirement_atis an optional RFC3339 timestamp ornull. The field is stored on the corresponding model alias and returned byGET /api/v1/models, so clients can recover migration guidance whenever they reload the catalog. Refreshing syncs or removes this metadata and leaves the default model alone while the registry still lists it. When the registry drops the default model, the default moves to theupgradetarget that model declared if the target still exists, keeping your thinking setting; otherwise the default and the thinking setting are cleared. Open sessions still using the dropped model switch to that target too, keeping their thinking level when the target supports it. To retire a model, declareupgradeon it first and keep it listed long enough for clients to refresh at least once, then remove it from the registry.On startup, the TUI prompts when the current model has a valid upgrade target, including after choosing a session to resume. The explanation is rendered as Markdown. The prompt waits until the editor is empty and no turn or dialog is active; if an approval or question interrupts it, it returns when the editor is idle again. Confirm with
Enter;Spacedoes not accept a migration. Accepting switches the model and keeps the current effort when the previous model supports thinking and the target supports that effort, otherwise the target's default effort is used; keeping the current model records the choice so that migration is not shown again. When the startup refresh finds that the registry dropped the default model, the TUI shows a warning and, if the current session uses that model, switches it to the replacement with the same effort rule, without asking.Besides the automatic startup refresh, you can trigger the same refresh manually at runtime:
/provider refreshre-fetches the model list of every provider, and/provider refresh <providerId>limits the refresh to a single provider. The command reports added and removed models per provider; a removed alias stops resolving for agents bound to it on their next turn, so removals are highlighted in the output.These fields are a Nexgen registry extension, not part of the models.dev schema:
json{ "upgrade": { "model": "new-model-id", "migration_markdown": "We recommend switching from {model_from} to {model_to}.", "retirement_at": "2027-01-01T00:00:00Z" } }
WARNING
NexgenK OAuth managed accounts logged in via /login do not appear in /provider. Use /login and /logout to manage them.
The same operations are also available in non-interactive environments via the shell command: nexgenk provider.
nexgenk
For connecting to Nexgen AI's OpenAI-compatible interface, including the NexgenK managed service and Nexgen Platform API keys.
- Default
base_url:https://ia.nexgen.systems/v1 - Credential key names:
NEXGEN_API_KEY,NEXGEN_BASE_URL - Additional capability: supports video upload
[providers.nexgenk]
type = "nexgenk"
base_url = "https://ia.nexgen.systems/v1"
api_key = "sk-xxxxx"
Router capabilities
The nexgenk provider speaks to NexgenRouter, which publishes what each model can do and gates the server tools per request.
- Model capabilities come from the router.
GET /v1/modelsreturns acapabilitiesblock per model (supports_vision,supports_function_calling,supports_reasoning). NexgenK reads it when the agent starts, so image input follows the router's declaration; a model without the block falls back to a local name heuristic. - Server tools run only on the surface their model speaks. Declare them with
[server_tools] enabled = [...]andNEXGEN_EXPERIMENTAL_SERVER_TOOLS=1. Chat models serveopenrouter:web_search,web_fetch,datetime,image_generation,fusion,advisor,subagentandexperimental__search_models;openrouter:tool_searchneeds a model whose protocol isopenai_responses:
[models.nexgen-auto-responses]
provider = "nexgenk"
model = "nexgen-auto"
protocol = "openai_responses"
max_context_size = 1048576
The edge picks the nexgen-tools-responses group itself when a /v1/responses request carries openrouter:tool_search; do not request that group by name.
- A 200 is not proof a server tool ran. Look at
usage.server_tool_use_details:tool_calls_executedonly appears when the provider executed the tool.nexgenk doctor toolsapplies the same rule. - Refusals carry
X-Nexgen-Motivo.tool_sin_politica,tool_no_permitida,tool_politica_expirada,tool_via_no_autorizada,tool_cuotaand the503kill switches arrive with the header; NexgenK reports the motive instead of a generic error and does not retry the permanent ones. - Files needs a grant. Listing (
GET /v1/tools/files) and deleting work when the key has the Files grant; without it the edge answers404 ruta_no_permitida. Uploading images to the model is done inline, because no endpoint serves a file's bytes. - Verify it with
nexgenk doctor tools. It probes models, search, fetch, Files, server tools andtool_search, and prints one ofMEDIDO,DENEGADO,BLOQUEADOorSIN-SONDAper row.
When using the NexgenK managed service, running
/loginautomatically configuresbase_urland credentials, so no manual setup is needed.
anthropic
For connecting to the Claude API. Standard Claude models automatically enable vision, tool use, and Thinking (where supported); custom or uncovered models need capabilities declared explicitly on [models.<alias>].
- Default
base_url: follows Anthropic SDK default - Credential key names:
ANTHROPIC_API_KEY,ANTHROPIC_BASE_URL - Default
max_tokens: inferred per model. To override, setmax_output_sizeon the model alias
[providers.anthropic]
type = "anthropic"
api_key = "sk-ant-xxxxx"

[models."claude-opus-4-7"]
provider = "anthropic"
model = "claude-opus-4-7"
max_context_size = 200000
# max_output_size = 32000  # optional; omit to use the model-inferred default
openai
For connecting to the OpenAI Chat Completions protocol, as well as any third-party service compatible with that protocol (override base_url as needed).
Third-party reasoning models (DeepSeek, Qwen, One API, etc.) work out of the box: the CLI automatically handles the reasoning_content field and reasoning_effort injection. If your gateway returns reasoning content under a non-standard field name, set reasoning_key on the model alias to override.
- Default
base_url:https://api.openai.com/v1 - Credential key names:
OPENAI_API_KEY,OPENAI_BASE_URL
[providers.openai]
type = "openai"
base_url = "https://api.openai.com/v1"
api_key = "sk-xxxxx"
openai_responses
Corresponds to OpenAI's newer Responses API, always operating in streaming mode. Configuration is the same as openai.
- Default
base_url:https://api.openai.com/v1 - Credential key names:
OPENAI_API_KEY,OPENAI_BASE_URL
[providers.openai-responses]
type = "openai_responses"
base_url = "https://api.openai.com/v1"
api_key = "sk-xxxxx"
google-genai
For connecting directly to the Google Gemini API. Thinking, vision, and multimodal capabilities are auto-detected by model name.
- Credential key name:
GOOGLE_API_KEY
[providers.gemini]
type = "google-genai"
api_key = "xxxxx"
To route through a Gemini-compatible proxy or gateway, set base_url (or the GOOGLE_GEMINI_BASE_URL env var); when omitted, the SDK default https://generativelanguage.googleapis.com is used.
Give the host root only. The Google GenAI SDK appends the API version and path itself (e.g.
/v1beta/models/<model>:generateContent), so a trailing/v1betawould produce a doubled/v1beta/v1beta/….
[providers.gemini]
type = "google-genai"
api_key = "xxxxx"
base_url = "https://your-gateway.example"
vertexai
Shares the same implementation as google-genai; setting type = "vertexai" switches to the Vertex AI access path.
Authentication follows the standard Google Cloud ADC flow (gcloud auth application-default login or a GOOGLE_APPLICATION_CREDENTIALS service account JSON); this part is unrelated to NexgenK. The project ID and region must be written in the [providers.vertexai.env] sub-table. Simply export GOOGLE_CLOUD_PROJECT in the shell will not be read by the CLI.
[providers.vertexai]
type = "vertexai"

[providers.vertexai.env]
GOOGLE_CLOUD_PROJECT = "my-gcp-project"
GOOGLE_CLOUD_LOCATION = "us-central1"gcloud auth application-default login # one-time authentication
nexgenkTo route Vertex requests through a custom (e.g. proxied) endpoint, set base_url (or the GOOGLE_VERTEX_BASE_URL env var); when omitted, the SDK default regional *-aiplatform.googleapis.com host is used. As with google-genai, give the host root only. The SDK appends /v1beta1/publishers/google/models/… itself.
OAuth and credential injection
The NexgenK managed service uses OAuth rather than static API keys. After running /login, the built-in authentication toolchain automatically writes and refreshes credentials, so no manual configuration is needed in config.toml for this.
Next steps
- Configuration files — full field reference for the
providersandmodelstables - Config overrides — credential resolution priority rules for providers
- Environment variables — credential key names per provider type